An engineering blueprint for establishing continuous evaluation benchmarks on production LLM agents.
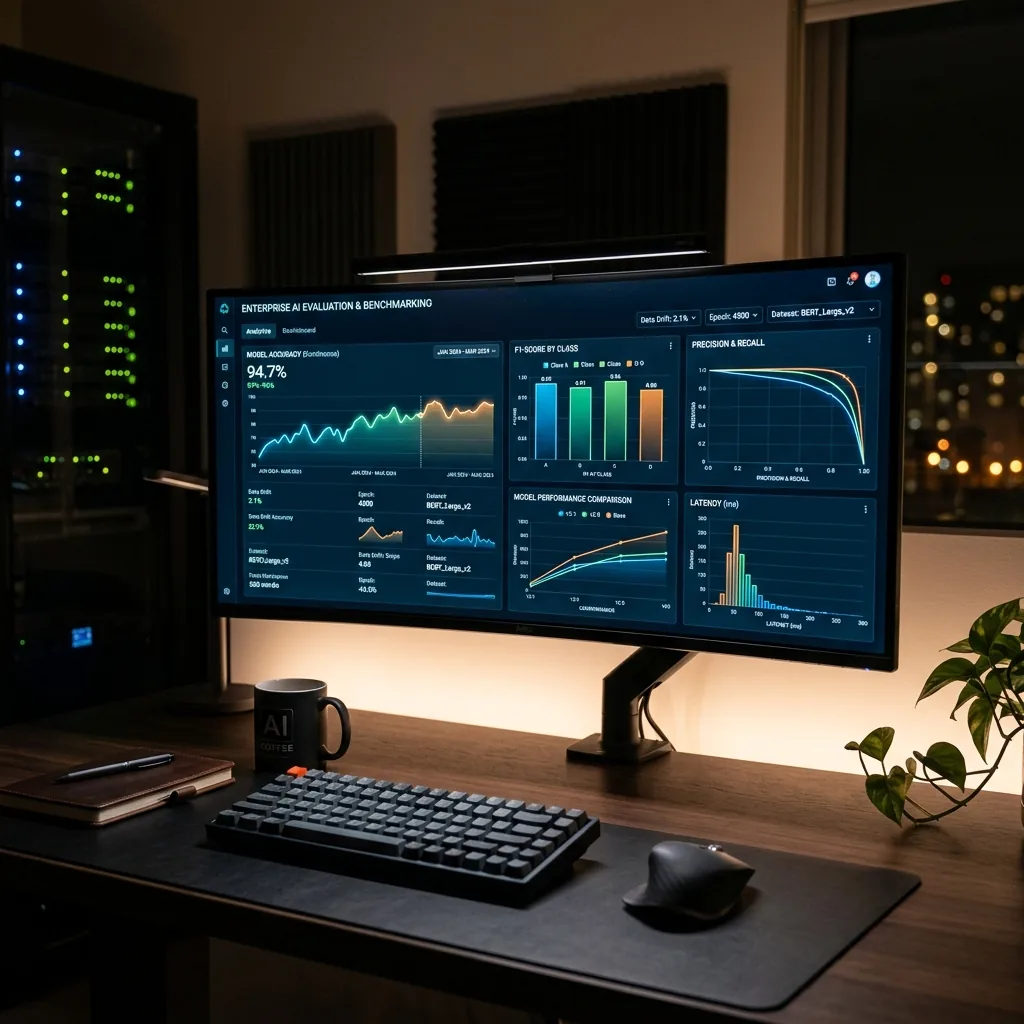
You can't improve what you can't measure, and "it looks good" doesn't survive contact with production. Shipping LLM features responsibly means treating evaluation as a first-class engineering system, run continuously — not a demo you eyeball once.
Why evaluation is hard for LLMs
- Outputs are open-ended, so exact-match assertions rarely apply.
- Small prompt or model changes cause silent regressions.
- Quality is multi-dimensional: correctness, safety, tone, cost, and latency.
Building an evaluation harness
We pin a versioned dataset of representative cases, score each output with a mix of deterministic checks and model-graded rubrics, and run the suite in CI so every change is measured before it ships.
for case in dataset:
    out = agent.run(case.input)
    scores = [check(out, case) for check in CHECKS]
    record(case.id, scores)
assert aggregate(results) >= BASELINE   # fail the build on regression
Treat prompts and models like code: versioned, tested, and gated on a benchmark that fails the build when quality drops.
With a standing eval suite, teams ship model and prompt changes with the same confidence they ship code — and catch regressions before users do.
Tagged Under
KoderTroop Systems Squad
Engineering Team
We are a collective of distributed systems engineers and architects at KoderTroop, focused on building resilient cloud infrastructure, multi-agent AI networks, and edge computing solutions.